 Synapse
Open Synapse
RL without TD learning
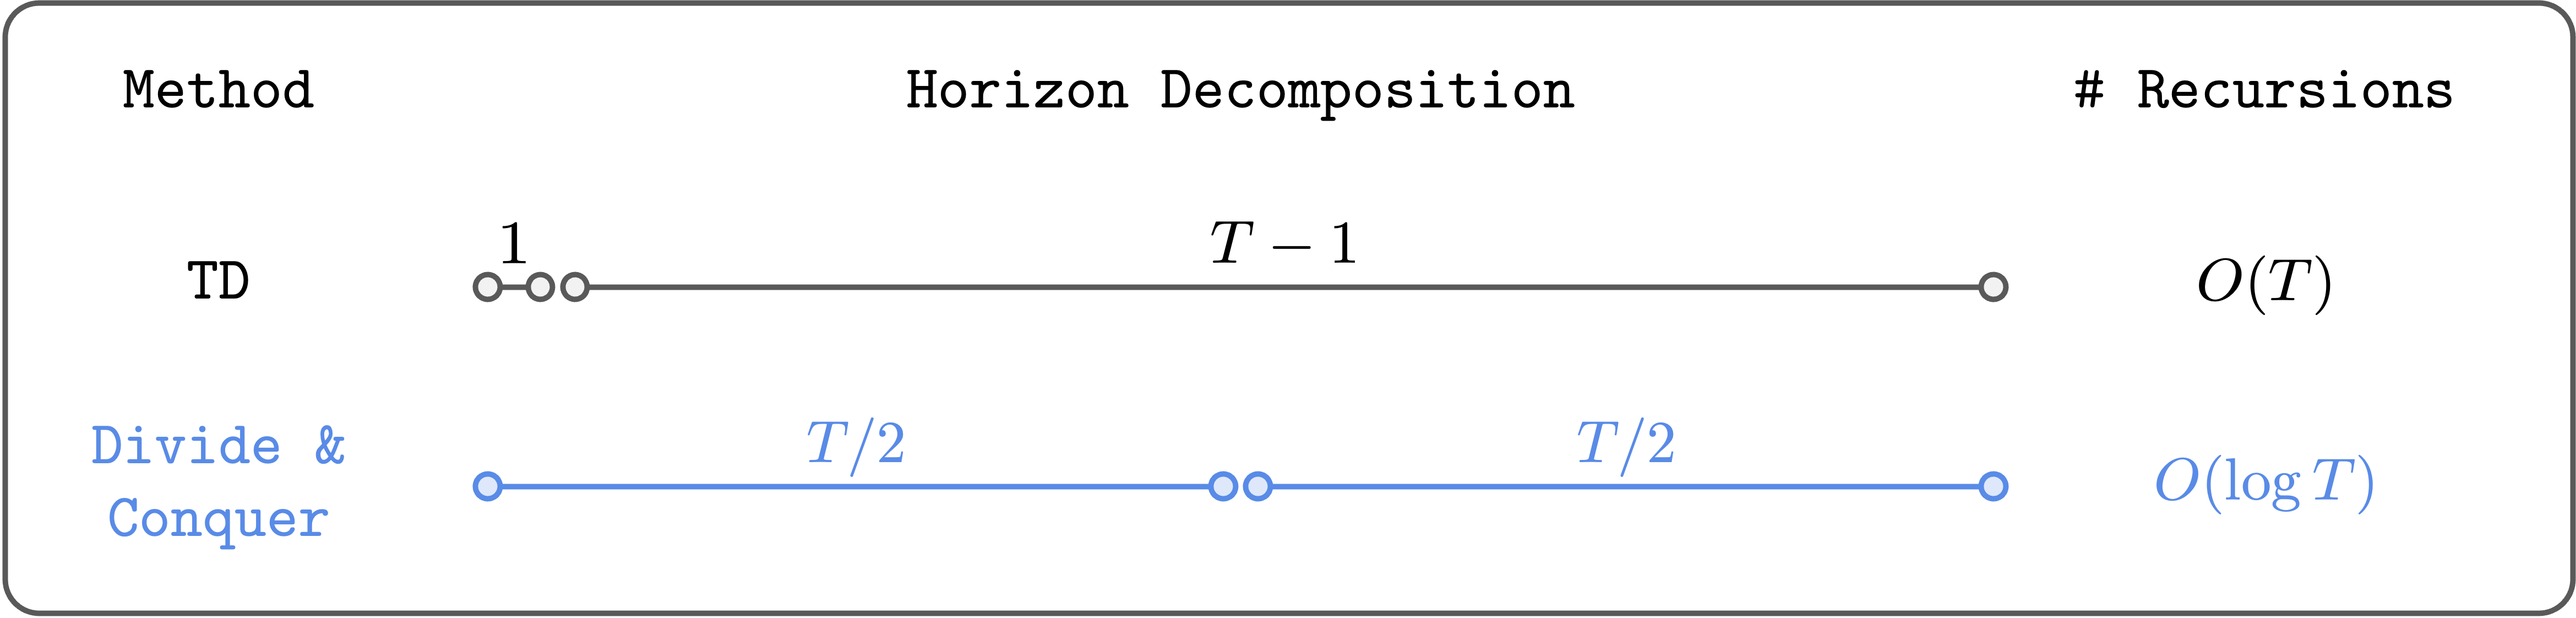
In this post, I’ll introduce a reinforcement learning (RL) algorithm based on an “alternative” paradigm: divide and conquer . Unlike traditional methods, this algorithm is not based on temporal difference (TD) learning (which has scalability challenges ), and scales well to long-horizon tasks.