 Synapse
Open Synapse
An open vision-language model for diverse medical applications
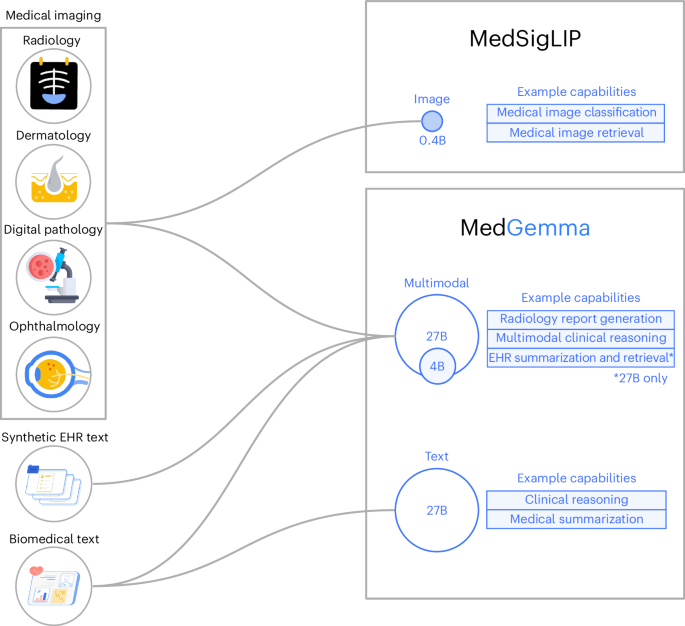
MedGemma, a collection of medical vision-language foundation models based on Gemma 3, demonstrates advanced medical understanding and reasoning across images and text and multiple medical imaging domains, exceeding the performance of similarly sized generative models while maintaining the general capabilities of the Gemma base models.